


AI PDF to Excel Table Extractor
DocuGenie uses AI to reconstruct visible PDF tables as rows and columns you can compare with the source. Upload a native or scanned PDF, review the generated table, and choose a download format. Formulas and original spreadsheet styling are not recovered from a PDF.
- Reconstruct visible headers, rows & columns
- Compare the generated table beside the PDF
- Check totals and values before reuse
Upload your document to get started
Drag and drop files here

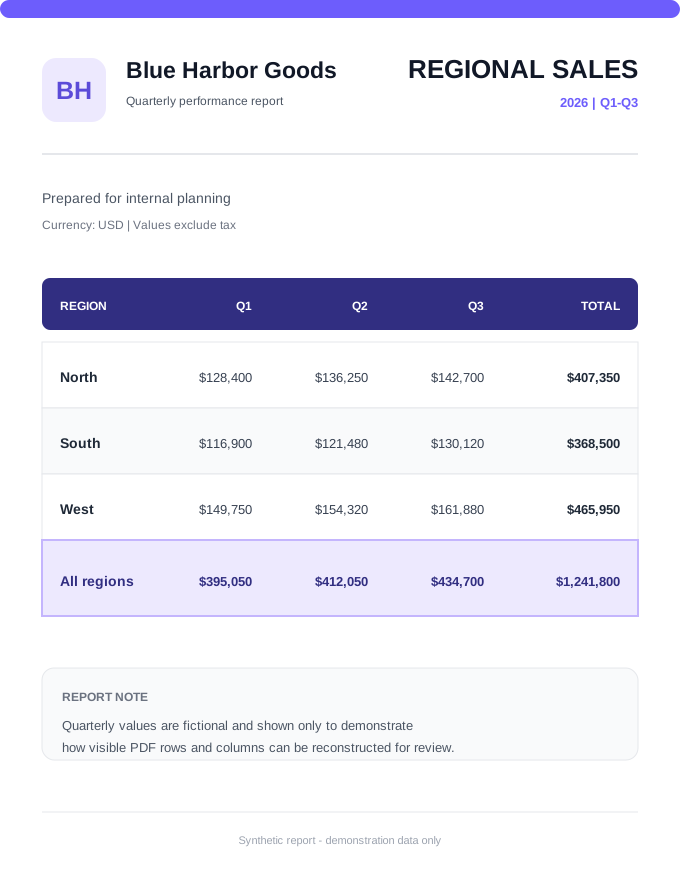
How to Convert a PDF Table for Excel
Upload the PDF
Add a native or scanned PDF. Anonymous processing accepts files up to 10 MB and reads the first three pages.
Extract visible tables
AI identifies visible headers, rows, and columns and returns each detected table as a generated review.
Compare and download
Check the generated table beside the source PDF, correct the review text where needed, and choose a download format.
What the PDF Table Extractor Returns
The result is a generated interpretation of visible table content, not the original spreadsheet hidden inside the PDF. Check every important value against the source.
Headers and Rows
Visible column labels and cell values are organized into a table for review.
Multiple Detected Tables
When the document contains several detectable tables, each is shown as a separate table section.
Source PDF Preview
Keep the uploaded PDF beside the generated result while checking rows, totals, and labels.
Native and Scanned PDFs
The workflow accepts text-based PDFs and image-only scans; scanned pages usually need closer review.
Editable Review Text
Correct the generated Markdown table before copying it or downloading a text-based review.
Visible Values Only
The extractor reads what appears on the page; it does not recover formulas or hidden workbook logic.
Review the Extracted Table Before You Reuse It
A table that looks plausible can still contain a wrong digit or shifted value. Compare the generated review with the PDF before calculating, importing, or reporting from it.
Check Numbers
Verify decimals, minus signs, percentages, currency symbols, and totals against the source.
Check Alignment
Confirm that every value stayed under the correct header when the PDF uses tight or uneven spacing.
Review Each Table
Inspect separately detected tables instead of treating the entire document as one continuous grid.
Correct the Review
Edit the generated table text when a header, label, or value needs correction.
Queue More PDFs
Keep several PDFs in the document list and review each completed result separately, subject to credits.
Copy or Download
Copy the edited review as plain text or choose a format from the download menu.
Native PDFs, Scans, and Table Limits
PDF table extraction rebuilds visible content as headers, rows, and columns. It cannot restore the original Excel formulas, hidden cells, workbook relationships, or styling that no longer exists in the PDF.
Native and scanned PDFs need different kinds of review
A native PDF contains selectable text, while a scanned PDF contains page images that must be read visually. Clear, straight scans provide better source material than blurred, faint, cropped, or rotated pages, but both types still require a source check.
Complex layouts can shift the grid
Merged cells, nested tables, multi-row headers, side notes, repeated page headers, and tables that continue across pages can move values into the wrong row or column. Treat the generated table as a reviewable first pass rather than a verified dataset.
Page and file limits
Anonymous processing accepts files up to 10 MB and uses the first three PDF pages. Signed-in processing accepts files up to 50 MB and a maximum of 50 pages per request. Available runs depend on the credits shown in the interface.
When PDF Table Extraction Helps
Use the general extractor when rows and columns are locked inside a PDF. Use a specialist finance tool when you need named fields such as invoice totals or bank transactions.
Financial Reports
Recover visible tables from annual reports and financial documents for checking before analysis.
Research Tables
Move published results into a reviewable table before rebuilding a chart or dataset.
Price Lists and Catalogs
Extract product codes, descriptions, and visible prices, then check wrapped rows carefully.
Public Data Reports
Turn statistical and government-report tables into data that can be checked against the publication.
Operations Reports
Review inventory, sales, and activity tables without recreating every row by hand.
Classroom Data
Reuse a table from a case study or worksheet in Excel or Google Sheets after verification.
PDF Table Extraction vs Copy and Paste
Use copy and paste for a small, clean table when it keeps the grid intact. Use table extraction when the PDF needs its visible rows and columns reconstructed for review.
| Feature | DocuGenie | Basic copy and paste |
|---|---|---|
| Attempts to separate headers, rows, and columns | ✓ | Depends on PDF |
| Shows the source beside the generated result | ✓ | ✕ |
| Keeps multiple detected tables separate | ✓ | Manual |
| Recovers original spreadsheet formulas | ✕ | ✕ |
| Requires checking against the source | ✓ | ✓ |
PDF to Excel FAQ
Common questions about using PDF to Excel
A PDF to Excel table extractor identifies visible table headers, rows, and columns and rebuilds them as structured data for a spreadsheet workflow. It reads what appears on the PDF page; it does not recover the original workbook, formulas, hidden cells, or spreadsheet logic.
Related Tools
Finance documents
Extract bookkeeping, expense, invoice, and statement data.
Bank Statement Parser
Extract account details and transaction rows from bank statement PDFs, scans, and images, then review the generated table beside the source.
Invoice to Excel
Extract invoice fields and line items in under 10 seconds, then export accounting-ready CSV or JSON.
Receipt Scanner
Scan receipt photos or PDFs into reviewable merchant, item, tax, total, and payment data.
PDF to Excel is one of 17 document tools in DocuGenie
Skip paying for a separate app for every task. One DocuGenie subscription bundles handwriting OCR, image-to-text, PDF and Excel conversion, translation, summaries, and more - from $9/mo. Use your credits on whichever tool you need.